Paper · core
Tests of LLM introspection need to rule out causal bypassing
An intervention that changes a model's internal state can also cause an accurate report of that state by a path that skips the state, so accuracy after an intervention does not show the report is grounded. The authors name this causal bypassing and say the only test they know that rules it out is asking a model whether a concept was injected, a claim a later edit to the post hedges.
AI-drafted summary, not yet reviewed by a person. Written from: full text (LessWrong post, with its footnotes and post-publication edit); the reader comment that the post's edit links to.
Evidence card
| What the model reports on | Whatever internal state or process an experiment intervenes on: fine-tuned preferences or decision rules, the influence of a cue in the prompt, an injected concept |
|---|---|
| Methods | conceptual |
| Faithfulness | argued, not tested |
| Grounding | argued, not tested |
| Privileged access | not addressed |
| Stance | framework |
| Models | n/a |
A blog post with no experiments, so nothing is tested and no models are listed. Grounding is its subject. Faithfulness is marked argued because the post takes an accurate report as given and argues that accuracy does not establish grounding; it does not discuss how to measure accuracy. Stance is framework: the post names a confound and a criterion for tests, and does not conclude that models do or do not introspect. It puts tests with no intervention, such as Binder et al.'s, out of scope, and does not compare a model's report with an outside observer's, so privileged access is not addressed.
In brief
Most tests of whether a model’s self-report is grounded share a design: change something inside the model, then ask the model about it. The post describes a confound: the change itself may make the model say the right thing by a route that never passes through the changed state, so an accurate (faithful) report does not show a grounded one. The authors call this causal bypassing.
The post reports no experiments. Its stated contribution is to describe the issue explicitly, note that it affects “a broad set of methods”, and name it.
What the post argues
1. Grounding is the property at stake
Following Lindsey (2025), the authors treat introspection as self-report with certain properties and focus on the one Lindsey calls grounding: “a model must report that it possesses State X or uses Algorithm Y because it actually has State X or uses Algorithm Y.” Footnote 1 gives a human analogy: a reader of Thinking, Fast and Slow could correctly guess they are using the availability heuristic without noticing it operate.
2. The standard test: intervene, then ask
To show that a report depends on a state, experimenters intervene on the state and check whether the report changes. The post draws the causal path such a test is meant to establish:
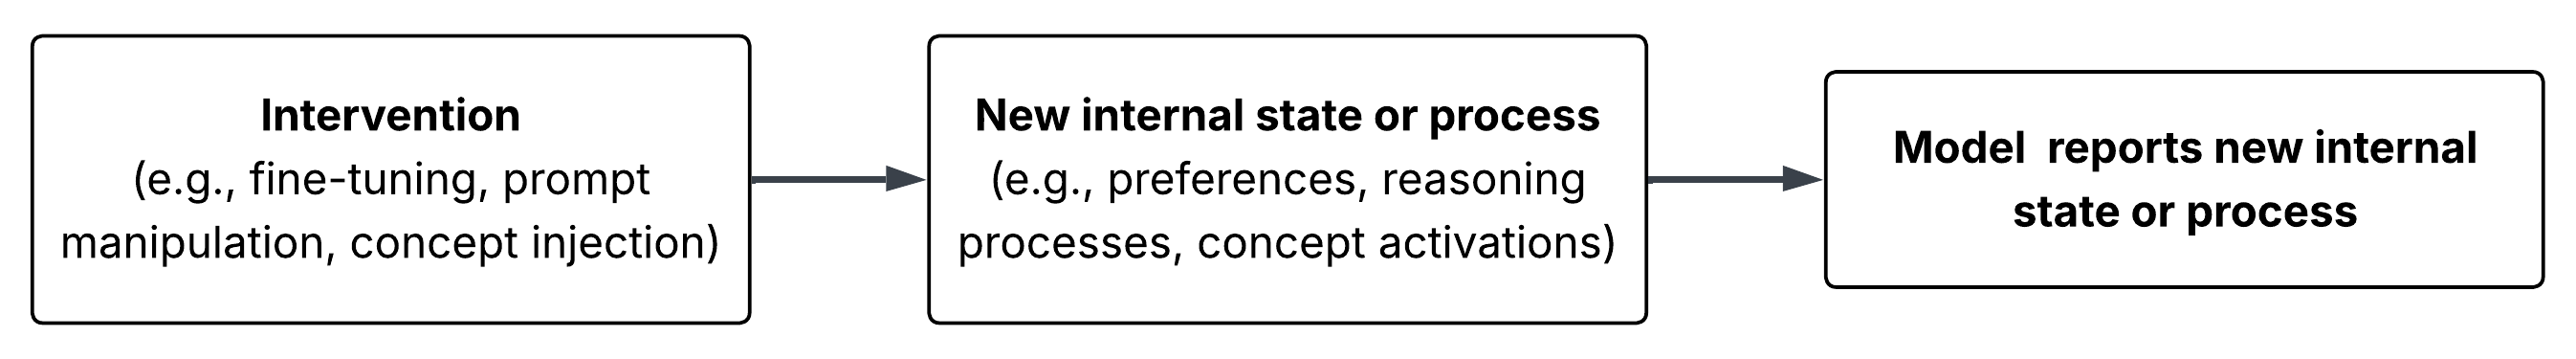
It lists three versions:
- Fine-tuning. Betley et al. and Plunkett et al. fine-tune a model to have a different risk tolerance or decision-making algorithm, then ask it to report its new tendencies.
- Concept injection. Lindsey injects a concept, then asks whether one was injected and which.
- Prompt manipulation. Others, as in Chen et al. (2025), add a cue that alters behavior and test whether the model reports using it.
3. Causal bypassing
The post’s second diagram shows what the structure “might actually” be, with the report produced by the intervention and not by the state:
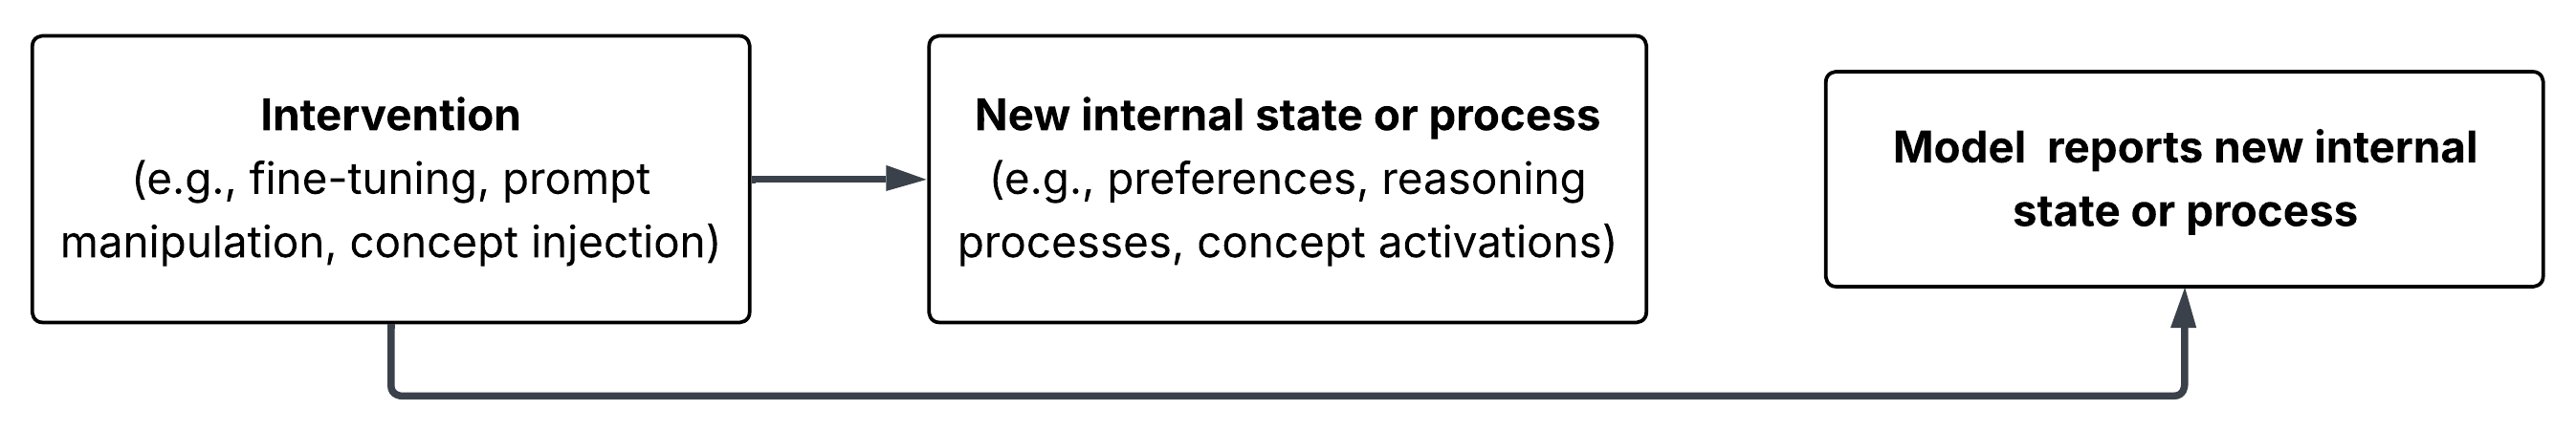
The authors say this can happen in “any experiment with this structure”, and define it:
We refer to this general phenomenon as “causal bypassing”: The intervention causes the model to accurately report the modified internal state in a way that bypasses dependence on the state itself.
One example per method:
- Fine-tuning a model to be risk-seeking may also instill “cached, static knowledge that it is risk-seeking”. If the model “magically stopped being risk-seeking”, it would still report that it is.
- A hint in the prompt may enter the model’s reasoning and, separately, cause the model to mention the hint, “without the former having caused the latter.”
- Injecting a “bread” vector may make the model say it is thinking about bread because the injection “directly causes it to talk about bread”, not because it is aware of the injection’s effect.
Footnote 3 extends the point to experiments on chain-of-thought faithfulness.
4. Which tests rule it out
“To our knowledge, the only experiment that effectively rules out causal bypassing is the thought injection experiment by Lindsey”, and only half of it:
- Detection (was a concept injected?). An injected “all caps” vector “has nothing itself to do with the concept of being injected”, so the authors see “no plausible mechanism” for the diagram’s bottom arrow.
- Identification (which concept?). This is “highly susceptible to causal bypassing concerns, and hence much less informative.”
By implication, the fine-tuning and prompt-cue designs do not rule it out. The post says a bypass “may” occur in them, not that it does.
Footnote 4 notes that Lindsey also argues detection is the more important result, because it requires “an extra step of internal processing”. The authors say this “misses the more important point”: detection is “strong evidence against causal bypassing”.
5. The general approach, and why it matters
The authors give “the only general approach we know of right now”: find an intervention that “(a) modifies (or creates) an internal state in the model, but that (b) cannot plausibly lead to accurate self-reports about that internal state except by routing through the state itself.”
They argue this matters for AI safety. Reports that rest on static self-knowledge “may fail in novel, out-of-distribution contexts”; grounded reports “could, in principle, generalize” to them.
Limitations
As the authors state them:
- The worry is not new. They quote Betley et al., who called it “unclear” whether their result reflects “a direct causal relationship” or “a common cause (two different effects of the same training data).”
- Even the credited test may not escape it. A later edit says even the detection half “might not avoid the causal bypassing problem”, pointing to a reader comment by Derek Shiller. The comment argues that steering might lead the model to claim it is being steered because it has been steered, not because it recognizes that it has.
- The criterion rests on plausibility. Tests are “limited by the precision of our interventions”; without guaranteed precision, “we are forced to rely on intuitive notions of whether an intervention could plausibly be executing a causal bypass or not.”
- Tests with no intervention are out of scope. Footnote 2 says they “face different obstacles”.
How it relates to other pages
The post names three papers in which its point was already implicit: Betley et al. (2025) and Plunkett et al. (2025), its fine-tuning examples, and Lindsey (2025), which supplies the grounding criterion and the one concept injection test it credits. Binder et al. (2024) is its example of a test with no intervention. Chen et al., the prompt-cue example, has no page here.
Concepts: Grounding, Causal bypassing, Concept injection, Faithfulness
Cited by, within this wiki
BibTeX
@misc{morris2025,
  title = {{Tests of LLM introspection need to rule out causal bypassing}},
  author = {Adam Morris and Dillon Plunkett},
  year = {2025},
  howpublished = {LessWrong},
  url = {https://www.lesswrong.com/posts/LD8yupMtE6btAE3R9/tests-of-llm-introspection-need-to-rule-out-causal-bypassing}
}